$ push the latest changes to staging▎
Talk faster
than you type.
Hold a key, talk, and your words land in any Windows app: terminal, editor, browser, chat. Free, open source, no account.
one-click install · auto-updates itself · Windows may warn it's unsigned: More info → Run anyway
↓ 2,364 downloads25 stars on GitHub
You say it once
push the latest changes to staging when you get a chance
routes to the focused app →
$ push the latest changes to staging
Listening ▍▎▌▅▂▆▃▍
Private by default
·
Free forever
·
Works in anything
·
Open source
See it in action
Watch it work — in 3 minutes.
A real walkthrough: dictating a full build into Claude Code by voice, the settings tour, per-app profiles, and going 100% offline.
The honest comparison
Free, private, and built for Windows.
The popular dictation apps are Mac-first, cloud-only, and cost up to $144/year. Here's the trade you're actually making.
| PipeVoice | Wispr Flow | Windows built-in | |
|---|---|---|---|
| Price | Free forever | $15/mo · $144/yr | Free |
| Your voice | Stays on your PC (offline option) | Uploaded to the cloud | Sent to Microsoft |
| Built for Windows | Native | Mac-first port | Basic |
| Works in any app | Yes | Yes | Limited |
| Works offline | Yes · local Whisper | No | No |
| Open source · auditable | Yes | No | No |
Comparison from public pricing & reviews, 2026. Bring your own key (cents/day) or run fully offline, free.
What it does
Less typing. No new habits.
Your words land in the app you're already in, pasted the moment you let go. No special box to copy from.
Works in anything
Terminal, editor, browser, chat box. Your words land in the focused window in one go, and whatever was on your clipboard, even a screenshot, is put back.
Private by default
Run the fully offline path (Local Whisper plus a local Ollama model) and nothing leaves your machine. No account, no telemetry, no servers of ours. Open source, so verify it.
Built for AI coding
Dictate prompts straight into Claude Code, Cursor, or any terminal, 3 to 5 times faster than typing them. It arrives knowing the words developers say: CLAUDE.md, npm, kubectl, pull request — typed the way you would, not the way a phone would guess. Talk the way you think.
Talk in commands
Say "new line", "new paragraph" or "tab key" to format as you go. Say "scratch that" to discard the last bit, or end with "send it" to type and press Enter hands-free. Toggle it on or off.
Dictation history
Every transcript is saved locally on your PC. Open the tray History window to re-copy anything you dictated earlier, marked typed or clipboard. Stored only on your machine, nothing uploaded.
It adapts to each app
Per-app profiles. PipeVoice spots the focused window and switches behaviour to match: raw text and a hands-free Enter in your terminal, polished and auto-sent in chat, no cleanup in your editor. Set the engine, cleanup, Enter and output once per app.
Made for the terminal
Claude Code's voice stops at the CLI.
PipeVoice doesn't.
Anthropic shipped /voice in 2026, but it only types inside the Claude CLI. Your editor, browser, Slack, Jira and terminal panes are still keyboard-only.
PipeVoice pastes your words into all of them. Hold a key, say the prompt, release, and it lands wherever your cursor is. You think at ~150 wpm and type at ~40. Close the gap.
The loop that sold me on it: Claude builds a UI, you flip to the browser to see the real thing, hold a key and talk your feedback to your clipboard, then paste it straight back into the prompt. /voice never leaves the CLI, so it can't do this.
› add rate limiting to the subscribe route
and write a test for the 429 path
⏺ editing api/subscribe.js …
and write a test for the 429 path
⏺ editing api/subscribe.js …
hold Ctrl + \ → types where your cursor is
hold Right Ctrl + Shift → to your clipboard
Ctrl + Alt + S → Social voice
Ctrl + Alt + P → Professional voice
hold F8 → pick any voice
hold Right Ctrl + Shift → to your clipboard
Ctrl + Alt + S → Social voice
Ctrl + Alt + P → Professional voice
hold F8 → pick any voice
A key for every voice
A hotkey for
every voice.
Your main key pastes into whatever app is focused; a second copies to your clipboard instead. Then bind any Voice to its own key — Social, Professional, Code — to dictate in that style instantly. Or hold the picker key to pop up the list and choose a voice on the fly.
Every voice
It speaks your accent.
Pick your English in the tray (British, US, Australian, Indian, New Zealand) and the engine loads the matching model. Not a native English accent? Just describe it in plain words, like "native Russian speaker" or "I stutter and use a lot of fillers", and the AI cleanup corrects for it.
Accent / language English · UK / British
Speech notes native Russian speaker
Speech notes native Russian speaker
App Profiles + Voices
One voice in. The right style out.
You talk the same way everywhere — PipeVoice decides how it lands. Voices are named polish presets you build once and reuse: Tidy Professional Code · Prompt. PipeVoice watches the focused window and applies that app’s Voice automatically — or bind one to a key.
You say it once
“push the latest changes to staging when you get a chance”
Heads up — pushing the latest to staging now, give it a few mins 🚀
Push the current branch to staging and confirm the deploy succeeds.
I’ll deploy the latest changes to staging shortly and confirm once it’s live.
just pushed the new stuff to staging if anyone wants to poke at it 👀
Push the latest changes to staging when you get a chance.
Or override on a key
CtrlAltP→Professional
CtrlAltC→Code
HoldF8→pick a Voice mid-sentence
A key always wins over the app’s default — drop into Professional for one sentence, then go back to talking normally. Profiles auto-detect the focused window and reset the moment you switch.
Also in the box
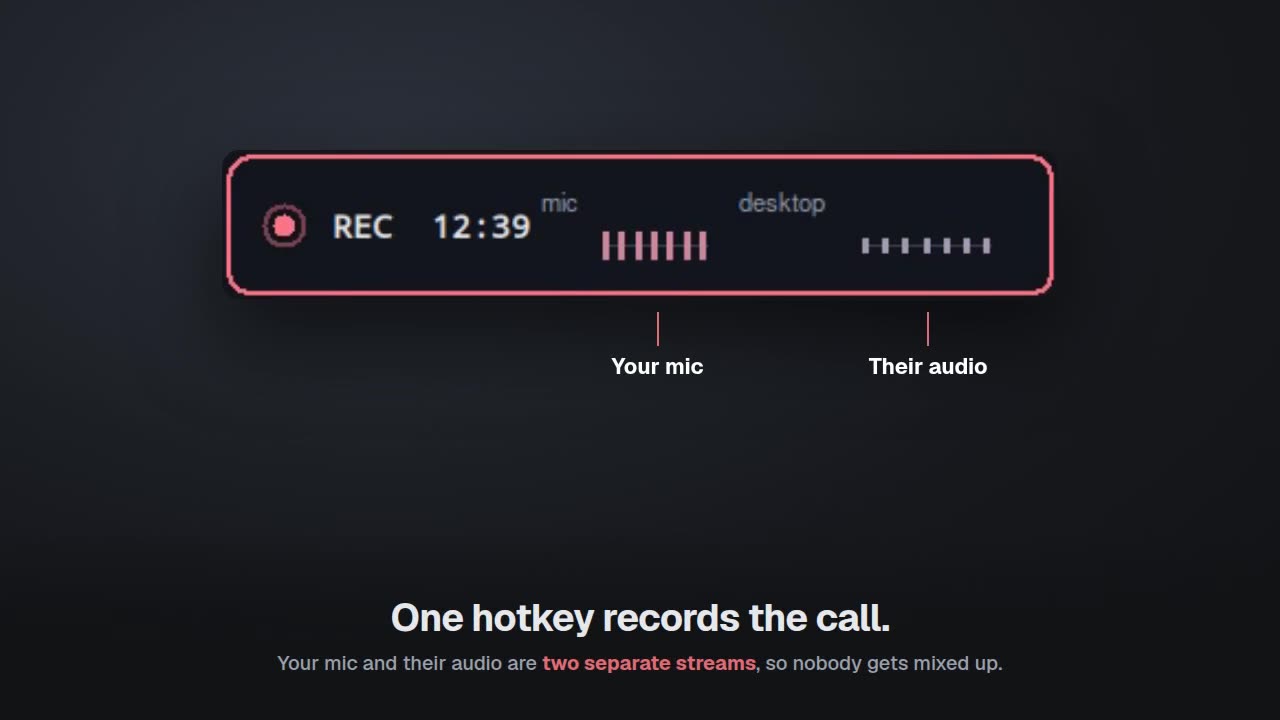
Both sides of the call. Never mixed up.
PipeVoice captures your microphone and your computer's audio as two separate streams, so what you said and what they said can't be confused.
See how meetings work →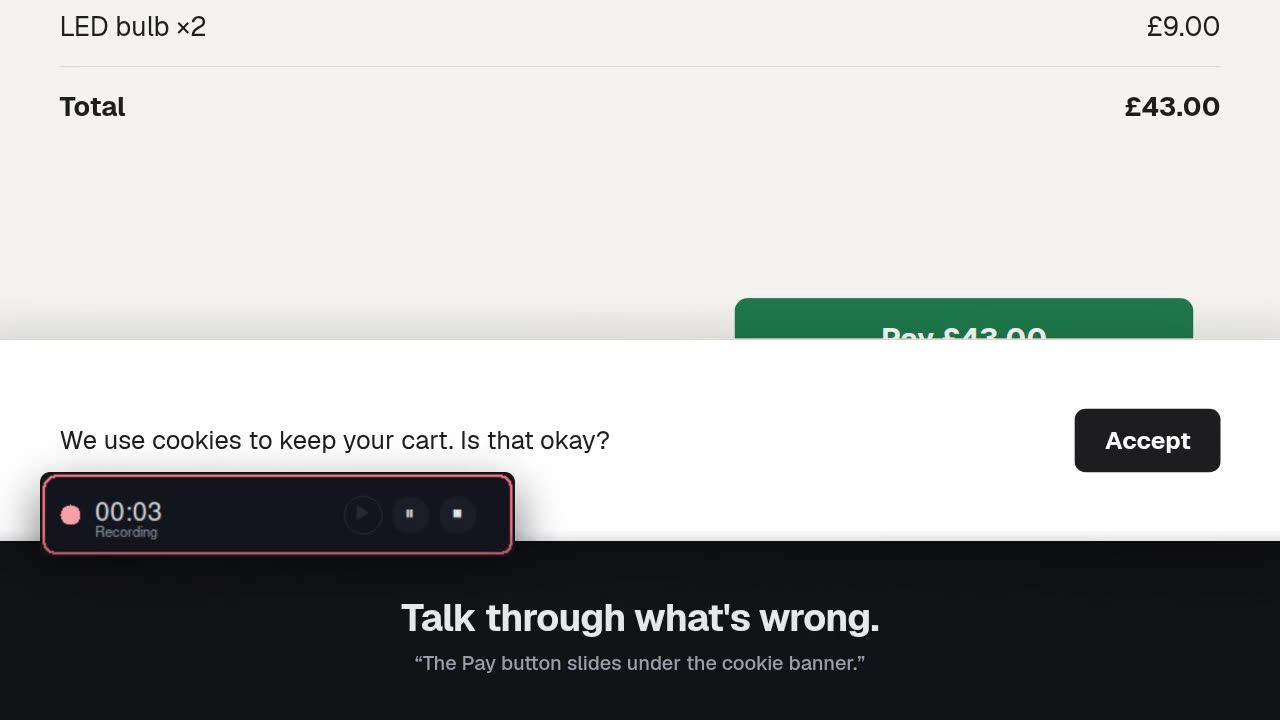
Stop describing the bug. Show it.
Press a hotkey, drag a box around the problem, and talk through what is wrong.
See bug recording →Point at anything on screen. Hear it.
Press a hotkey, drag a box around any text, and it reads it to you.
See read-aloud →Your stack, your call
Works with your whole stack.
Two stages, your choice at each. Pick where your words go on a spectrum: use the cloud you already pay for, run it free, or keep every byte on your machine. Same hotkey, same typing, different trade.
CloudYour key, your provider. Deepgram streams live words as you speak, Groq runs real Whisper fast and cheap. Audio goes to the provider you chose, never to us.
FreeNo OpenAI credit required. Polish your text with Google Gemini's free tier or a free OpenRouter community model. Most people already have a Google account.
Fully offlineLocal Whisper transcribes, a local Ollama model polishes. No key, no cost, no internet. Nothing ever leaves your PC. The privacy maximalist's setup.
transcribe Local Whisper · no key
polish Ollama · llama3.2
⏻ network calls this session: 0
polish Ollama · llama3.2
⏻ network calls this session: 0
Transcribespeech to text
Geminifree tier — one key also does the polishFreeDefault
Groq Whisperreal Whisper, near-instant, ~9× cheaperFast & accurateFree key
Deepgramstreaming, live words as you speakStreams live$200 free
Local Whisperfaster-whisper on your machineOfflineNo key
Polishoptional Flow-mode cleanup: fillers, casing, punctuation
Google Geminifree tier — the same key as transcriptionFreeDefault
OpenAIoptional, if you keep a key aroundYour key
OpenRouterfree community modelsFree
Ollamaa local LLM on your boxOfflineNo key
The default is one free Gemini key — it transcribes and polishes, no card. Want zero internet? Pair Local Whisper with Ollama for a 100% offline, key-free pipeline. Cloud connectors use your own key, so audio goes only to the provider you picked, never to us. Privacy.
Setup
Running in a minute
01
Install
Download, run the installer. It opens quietly to your system tray.
02
Pick your connectors
Two stages, your call at each. Transcribe with free Gemini, Groq Whisper, Deepgram or local Whisper, then polish with free Gemini, OpenAI, OpenRouter or local Ollama. The default is one free Gemini key for both — or pair local Whisper with Ollama to stay fully offline.
03
Hold & talk
Hold the hotkey, speak, release. Your words land where your cursor is.
Stay in the loop
Get build notes & early access to Pro.
I ship updates often: new connectors, better accuracy, and an optional managed-key Pro for people who'd rather not touch an API key (PipeVoice itself stays free). Drop your email and I'll keep you posted. No spam, unsubscribe anytime.
no spam · just shipping updates
Good to know
Questions
Is it really free?
Yes, free forever. Run the fully offline path (local Whisper plus Ollama) at zero cost, polish for free with Google Gemini or OpenRouter community models, or bring your own Groq or Deepgram key and pay the provider directly (cents a day). A managed-key Pro is coming later for people who want zero setup, but the core tool stays free.
How is this different from Wispr Flow?
PipeVoice is free (no $144/yr subscription), built Windows-first instead of a Mac port, and fully open source so you can read every line. It also gives you the choice Wispr Flow doesn't: pick your transcription engine and your AI-polish provider separately. Use the cloud with your own key, polish for free with Gemini or OpenRouter, or run the whole pipeline 100% offline with local Whisper and Ollama.
Can it handle my accent?
Pick your English variant in the tray (British, US, Australian, Indian, New Zealand) and the engine switches to the matching model. For a non-native accent, a stutter, or heavy filler words, add a line of "speech notes" like "native Russian speaker" and the AI cleanup adjusts for it. The engines are trained on a wide range of accents to begin with.
Can I dictate to my clipboard instead of typing?
Yes. A second hotkey (Right Ctrl + Shift by default, and configurable) records and copies the result straight to your clipboard without pasting into the focused window. Handy for giving feedback while you read one window, then pasting into another.
Windows says "unrecognised app": is it safe?
Yes. That SmartScreen warning shows for any app without a paid code-signing certificate. Click More info → Run anyway. It's open source, read every line on GitHub.
Is my voice uploaded anywhere?
Only to the connector you pick, and never to us. A cloud transcription engine (Gemini, Groq or Deepgram) sends your audio to that provider on your key. Local Whisper sends nothing. The optional polish stage only ever sends text, not audio: OpenAI, Gemini and OpenRouter receive the transcript to clean up, while a local Ollama model keeps even that on your machine. Pick local Whisper plus Ollama and zero bytes leave your PC. PipeVoice has no servers and no telemetry.
Which engine should I use?
It's a two-stage choice. For transcription: free Gemini is the default (one key also polishes), Groq runs Whisper fast and cheap, Deepgram streams live words as you speak, and local Whisper runs fully offline with no key. For optional polish: free Gemini by default, OpenAI if you keep a key, OpenRouter, or local Ollama to stay offline. Pair local Whisper with Ollama and the whole pipeline is free, key-free and 100% offline. Switch either stage any time from the tray.
Can I say "new line" or "send it" while dictating?
Yes. Voice commands are built in and toggleable: say "new line", "new paragraph" or "tab key" to format, "scratch that" or "cancel that" to discard, and end with "send it" or "press enter" to type your text and submit hands-free.
Are my past dictations saved? Can I get them back?
Yes. Every transcript is saved locally on your PC. Open the History window from the tray to re-copy anything you dictated earlier, marked typed or clipboard. It's local only, with nothing uploaded, and you can clear it whenever you like.
Can different apps behave differently?
Yes, that's per-app profiles. PipeVoice sees which app is focused and applies that app's settings automatically: the transcription engine, whether the AI cleans up your text, and whether it presses Enter for you. Set your terminal to raw text with a hands-free Enter, your chat apps to polished and auto-sent, your editor to no cleanup, then never think about it again. Add a profile from the tray and pick the app from a searchable list.
Is there a word limit?
No. PipeVoice does not count or cap words, and there is no trial wall. If you pick a cloud engine such as Deepgram or OpenAI Whisper you pay that provider directly for the audio you send, on your own key. Local Whisper is free with no key.
Is PipeVoice open source?
Yes. PipeVoice is MIT-licensed and the code is at github.com/Powleads/PipeVoice, so you can read exactly what it does.
Does PipeVoice work offline?
Yes. Choose the Local Whisper engine (a model of about 150 MB that runs on your CPU, no GPU needed) and optionally Ollama for AI cleanup, and nothing leaves your PC. Cloud engines need internet and your own key; if a cloud engine fails, PipeVoice retries that utterance on Local Whisper.
Does PipeVoice work with Claude Code, Cursor and ChatGPT?
Yes. PipeVoice pastes your words into whichever window has focus, then puts your clipboard back, so it works in a terminal running Claude Code, in Cursor, and in any other window that accepts text, including ChatGPT in a browser or the desktop app. Per-app profiles let each app get its own behaviour.
What languages does PipeVoice support?
The language picker offers auto-detect, English in five variants (US, UK, Australian, Indian, New Zealand), and Spanish, French, German, Portuguese, Italian, Dutch, Japanese and Chinese.
Do I need an account to use PipeVoice?
No. There is no account and no telemetry. Cloud engines use your own API key, stored locally on your PC; Local Whisper needs no key at all.